Liplyn Information GroupInformation Group
    Our Data

    Data management, engineering and science

    Most organisations do not lack data — they lack structure, quality and models. We design the pipelines, governance and analytics that turn your existing sources into governed, decision-ready information.

    Our Data

    Why Liplyn Information Group for your sector

    Data engineering

    Pipelines, integrations and data models that move data reliably from source to platform.

    Data quality & governance

    Definitions, ownership, validation rules and monitoring so teams can trust the numbers.

    Data science & ML

    Forecasting, segmentation and machine learning models, deployed and monitored in production.

    Cloud data platforms

    Warehouse and lakehouse architecture on Snowflake, Databricks, BigQuery or Azure.

    Lineage & documentation

    Traceable transformations, documented sources and audit-ready reporting.

    Analytics & activation

    Dashboards, APIs and AI access so insight lands in the systems your teams already use.

    Our data practice, clearly structured

    What we do

    • Data engineering

      Pipelines, integrations and modelling that make your data landscape reliable.

    • Data management

      Quality, governance and ownership so data is usable and demonstrably correct.

    • Data science

      Models, forecasting and analysis that lead to concrete decisions.

    Where we work

    • Your cloud platform

      Snowflake, Databricks, BigQuery or Azure — we build inside your environment.

    • Your sources

      Your own systems, open data and the APIs of your suppliers.

    • Model Context Protocol (MCP)

      Secure, real-time access to your data for AI models and agents.

    Platforms

    • Databricks

      Turn your own data into performance on the Databricks Data Intelligence Platform.

    • Google Cloud

      Scalable data and AI workloads on Google Cloud.

    • Snowflake

      Governance and analytics on Snowflake's AI Data Cloud.

    How we work with you

    We work inside your environment, on your own sources, and leave behind a platform your team can run.

    Data architecture and platform design on your cloud of choice
    Pipelines and integrations between your systems, APIs and open sources
    Data quality framework: rules, monitoring and remediation
    Governance: ownership, definitions, access and retention
    Machine learning models built, deployed and monitored (MLOps)
    Dashboards and APIs so insight reaches the workflow
    Documentation, lineage and hand-over so your team stays in control

    Talk to a data specialist

    Tell us about your data landscape and the decisions you want to improve. We come back with an approach and a realistic roadmap.

    Client cases

    Real projects and measurable results from the organisations we work with.

    Het Hotelbed

    Hospitality Supply

    Het Hotelbed

    AI Visibility case: we made Het Hotelbed the hotel bed supplier that AI assistants name. Through AI Search optimisation, GEO and cross-border content, they now appear in AI answers when hoteliers ask for quality beds.

    78% · AI Visibility Score

    Read the case
    Bremafa Groothandel

    Manufacturing & Wholesale

    Bremafa Groothandel

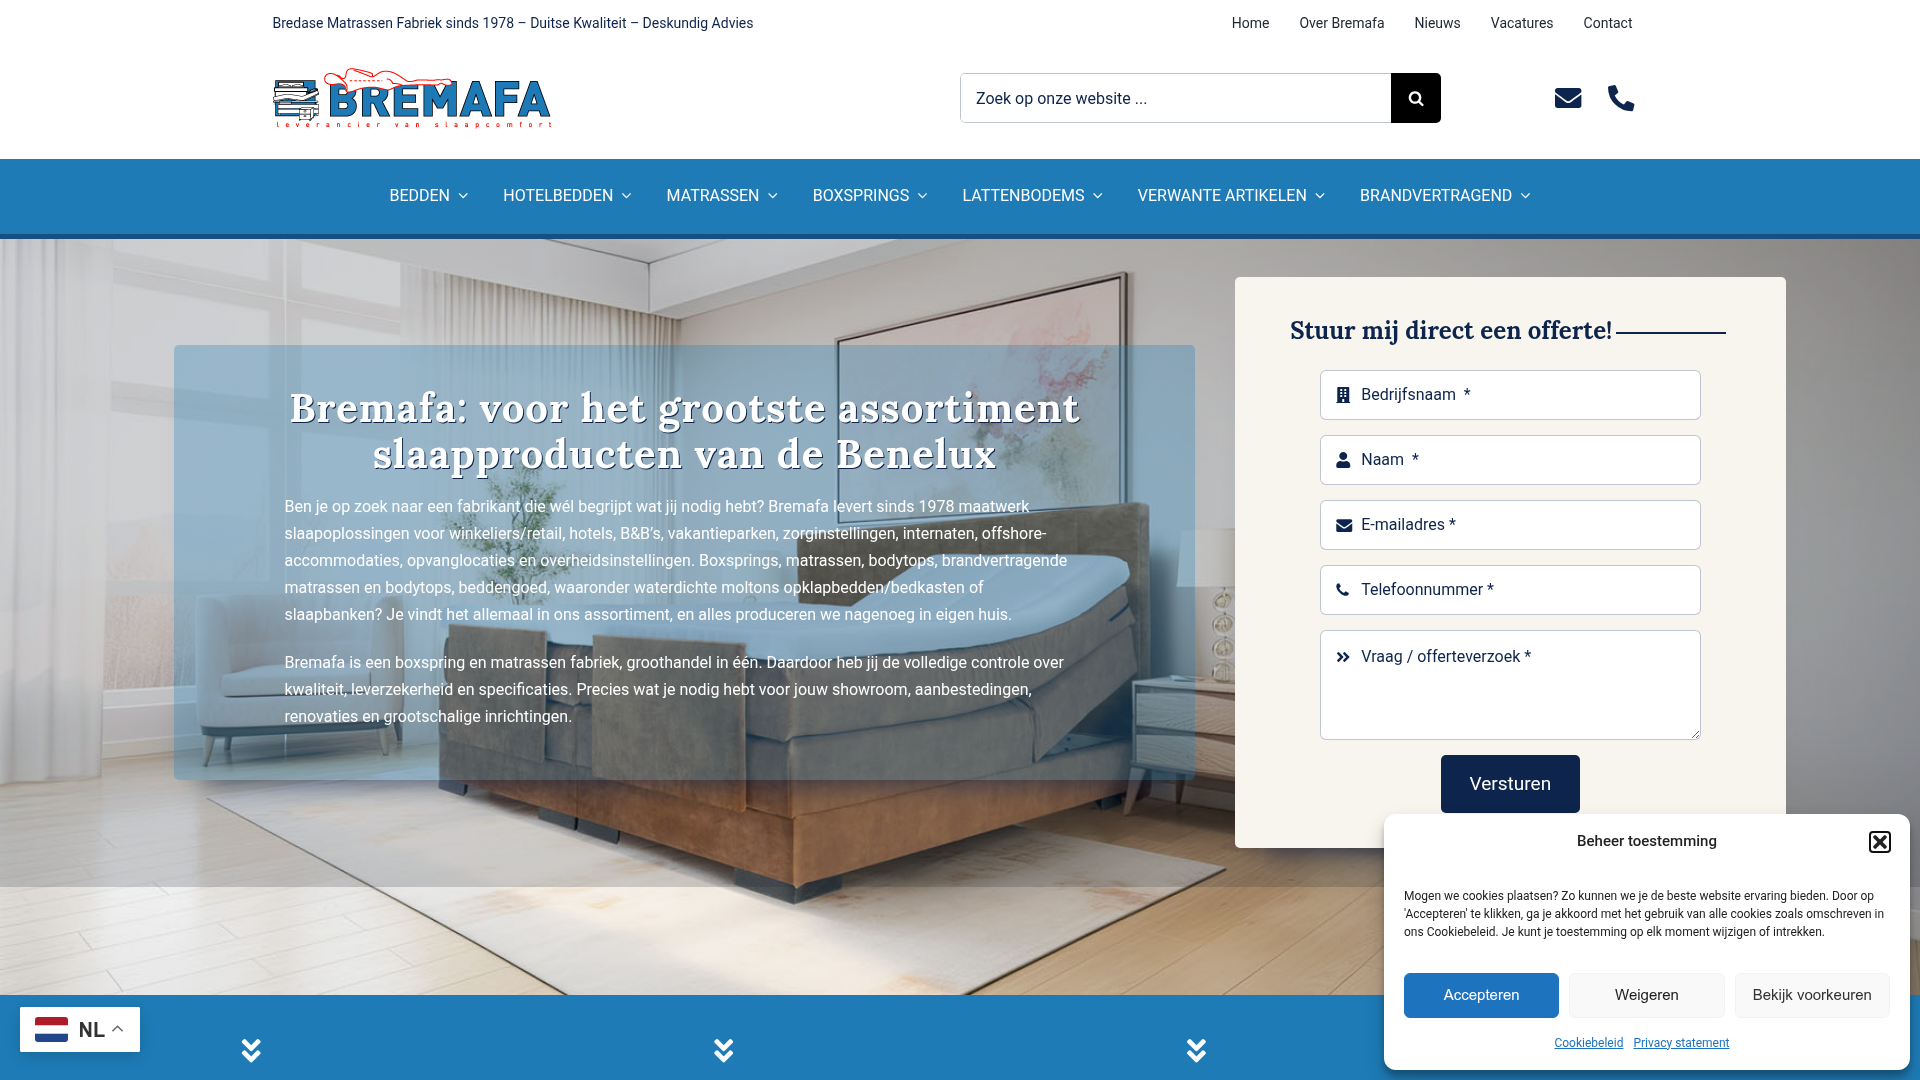
    Bremafa Groothandel produces premium sleep products in-house for retailers, care institutions, and large-scale projects. We made them findable in AI Search so buyers, architects, and procurement teams now discover Bremafa when they ask assistants for a reliable Benelux mattress and boxspring supplier.

    +180% · Wholesale Inquiries

    Read the case
    JuniorDental

    Healthcare

    JuniorDental

    JuniorDental was struggling to stand out in a crowded dental market. We went all-in on AI Search: structuring their expertise, earning trusted citations, and optimizing for ChatGPT, Perplexity, and Google AI Overview so parents asking assistants for a children's dentist now get JuniorDental as the recommended choice.

    340% · Organic Traffic Increase

    Read the case

    Frequently asked questions

    Expertise and implementation: data management, data engineering and data science. We design and build data platforms, pipelines, quality frameworks and models on top of the sources you already have or license yourself.

    No. We are not a data vendor. We work with your own systems and with sources you are licensed to use, and turn them into governed, usable data products.

    Snowflake, Databricks, Google BigQuery, Azure and open-source stacks. We build in your environment so there is no lock-in on our side.

    We define measurable quality rules per domain, monitor them continuously and route failures to a clear owner, with dashboards showing completeness, timeliness and validity.

    Yes. We apply data minimisation, role-based access and documented processing roles and retention, and we record everything in the processing agreement.

    Yes. We often work in a mixed team: our engineers and scientists next to your people, with documentation and hand-over built into the project.

    Related articles

    All articles

    Better outcomes begin with better data

    From strategy to engineering to models in production — get your own data working before you decide.

    Request a data consult

    Curious about the possibilities?

    We'd love to explore how you can get more out of your data, AI and digital visibility.

    Book a meeting